

How to Make an App Like Roam Research
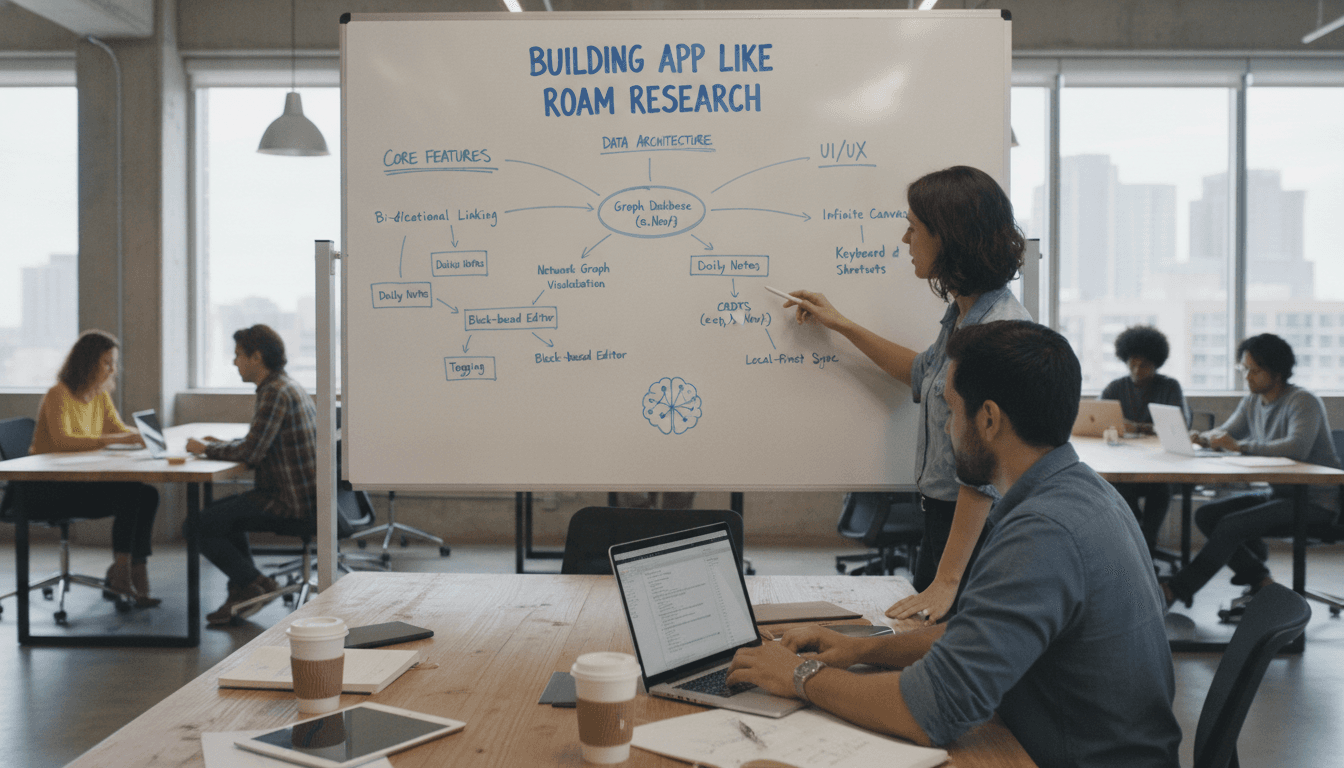
How to Make an App Like Roam Research
Roam Research changed the way people think about note-taking. Instead of forcing ideas into folders and hierarchies, it treats every note as a node in a graph, connected to other notes through bidirectional links. The result is a "tool for networked thought" — a personal knowledge base that grows more valuable the more you use it.
If you're planning to build something similar, this guide walks through the product thinking, architecture, features, and costs involved in creating a networked note-taking app.
What Makes Roam Research Different
Before writing a single line of code, it's worth understanding why Roam earned such a devoted following. Traditional note apps are digital filing cabinets. Roam is closer to a brain.
Block-based architecture. Every bullet point is a discrete, addressable block with its own unique ID. Blocks can be referenced, embedded, and nested infinitely. This is the foundational decision that everything else depends on.
Bidirectional linking. When you link from Note A to Note B, Note B automatically knows about it. The "Linked References" section at the bottom of every page surfaces this context without any manual effort.
Daily notes as the default entry point. Rather than asking "where should this go?", Roam opens to today's date. You write, you link, and organization emerges as a byproduct.
The graph view. A visual map of how ideas connect, which is part utility and part delight.
Query and filter capabilities. Users can build dynamic views that pull blocks from across the graph based on tags, attributes, and conditions.
Your app doesn't need to copy all of these. But you should understand which ones constitute the core value proposition versus which are nice-to-haves.
Step 1: Define Your Angle
The personal knowledge management (PKM) space is crowded. Obsidian, Logseq, Notion, Tana, Capacities, and RemNote all occupy adjacent territory. Launching a generic Roam clone in 2024 is a hard sell.
Successful differentiation usually comes from one of these directions:
- A specific audience. Academic researchers who need citation management. Lawyers building case knowledge. Writers structuring long-form work. Medical students cramming for boards.
- A storage philosophy. Obsidian won significant market share purely by storing notes as local markdown files that users own outright.
- An interaction model. Mobile-first capture, voice-driven input, or AI-assisted linking rather than manual
[[brackets]]. - A collaboration model. Roam's multiplayer story has always been weak. Real-time collaborative graphs remain an underserved niche.
- Pricing. Roam's $15/month price point left room underneath it, which Logseq and Obsidian exploited.
Pick your angle before you architect, because it changes fundamental technical decisions.
Step 2: Design the Data Model
This is the most important engineering decision you'll make, and it's very difficult to change later.
Blocks as the Atomic Unit
Each block needs, at minimum:
Block {
  id: UUID
  content: string          // raw markdown/text with inline syntax
  parentId: UUID | null
  pageId: UUID
  order: integer or fractional index
  children: UUID[]
  createdAt, updatedAt
  refs: UUID[]             // outbound links parsed from content
}
Pages are a special kind of block — a root node with a title. This uniformity keeps the system elegant: you can reference a page or a block with the same mechanism.
Ordering Children
Naive integer ordering forces you to rewrite every sibling's index on reorder. Use fractional indexing (assigning a value between the neighbors, e.g. between 1.0 and 2.0 you insert at 1.5) or a linked-list approach with nextSiblingId pointers. Fractional indexing is generally easier to reason about and works well with conflict resolution.
Storing the Link Graph
When a block's content is saved, parse it for [[page links]], ((block refs)), and #tags, then write those relationships into a separate index or join table. Don't compute backlinks by scanning every block at read time — that won't scale past a few thousand notes.
A graph database (Neo4j, Dgraph) is tempting, but most teams do fine with Postgres plus a well-indexed references table. Roam itself was built on Datascript/Datomic, a triple-store model, which is worth studying if you want maximum query flexibility.
Local-First and Sync
Users expect notes to work offline and sync instantly across devices. This is genuinely hard. Your options:
- CRDTs (Yjs, Automerge, Loro) — automatic conflict resolution, excellent for real-time collaboration, but adds document size overhead and complexity.
- Operation logs — record every change as an append-only event and replay. Simpler to debug, requires your own merge logic.
- Last-write-wins per block — the pragmatic choice. Because blocks are small and granular, conflicts are rare and the blast radius is tiny.
For a v1, per-block LWW with a sync queue is often the right tradeoff. Adopt CRDTs when collaboration becomes a headline feature.
Step 3: Build the Editor
The editor is the product. Users spend 95% of their time inside it, and if it feels laggy or fights their muscle memory, nothing else matters.
Don't build a text editor from scratch. Use a framework:
- ProseMirror / TipTap — mature, extensible, excellent schema control.
- Lexical (Meta) — performant, modern, good plugin architecture.
- CodeMirror 6 — great if you want a more markdown-source-oriented experience.
Editor requirements to plan for:
Tab/Shift+Tabto indent and outdent blocksEnterto create a sibling, with smart handling inside lists and code blocks- Collapse/expand triangles with persisted state
- Drag-and-drop block reordering, including whole subtrees
- Autocomplete popovers on
[[,((,/, and# - Inline rendering of references as clickable chips
- Multi-block selection and bulk operations
- Zoom into any block so it becomes the page root (breadcrumbs included)
Performance matters more than you think. A power user's daily notes page can contain thousands of blocks. Virtualize long lists, memoize aggressively, debounce saves, and keep re-renders scoped to the block that changed rather than the whole outline.
Step 4: Implement the Signature Features
Linked and Unlinked References
Linked references query your reference index for all blocks pointing at the current page. Unlinked references do a full-text search for the page title in blocks that don't yet link to it, then offer a one-click "Link" action. Unlinked references are a surprisingly strong retention feature — they create serendipitous rediscovery.
Block References and Embeds
A block ref ((uuid)) renders the source block's text inline, live-updating when the source changes. An embed renders the block and its entire child tree. Both need careful handling of circular references and orphaned IDs when a source block is deleted.
Daily Notes
An infinite-scroll feed of date-titled pages. Auto-create today's page on open. This single design choice removes the friction of deciding where a thought belongs, and it's arguably the highest-leverage feature to copy.
Graph View
Use a force-directed layout library — D3-force, Cytoscape.js, or Sigma.js for larger graphs. Rendering thousands of nodes in SVG will crush the browser, so switch to Canvas or WebGL beyond a few hundred nodes, and offer filters by tag, recency, and connection count.
Search
Full-text search across blocks with fuzzy matching. Client-side options like FlexSearch or MiniSearch work well in a local-first architecture; Postgres full-text search or Typesense/Meilisearch work for server-side. Search needs to feel instantaneous — under 50ms perceived latency.
Queries
Roam's {{query}} syntax lets users build dynamic views. Even a simplified version — "show me all blocks tagged #todo that aren't marked DONE" — delivers enormous value and turns the app into a lightweight task and project system.
Step 5: Choose Your Tech Stack
A pragmatic, battle-tested combination:
Frontend (web): React or Svelte, TypeScript, TipTap or Lexical for editing, Zustand or Jotai for state, Tailwind for styling.
Local persistence: IndexedDB via Dexie, or SQLite in the browser via WASM (wa-sqlite, SQLite WASM with OPFS) for much better query performance on large graphs.
Backend: Node (NestJS/Fastify) or Go, Postgres for primary storage, Redis for presence and pub/sub, S3-compatible object storage for attachments.
Sync layer: WebSockets for live updates, with an HTTP fallback for batch reconciliation on reconnect.
Mobile: React Native or Flutter if you want shared code; native Swift/Kotlin if the editing experience needs to feel exceptional. Mobile editing of deeply nested outlines is genuinely difficult — consider making mobile a capture-and-review surface rather than a full editor, at least initially.
Desktop: Electron or Tauri. Tauri produces dramatically smaller binaries and lower memory usage, which matters for an app users keep open all day.
Step 6: Layer in AI Thoughtfully
AI is where new PKM apps can genuinely leapfrog Roam, which was designed before LLMs were practical.
High-value applications:
- Automatic link suggestions. Embed each block, then surface semantically related notes the user hasn't linked yet. This is the AI-native version of unlinked references.
- Semantic search. "What was I thinking about pricing last spring?" should work even without exact keyword matches. Store embeddings in pgvector, Pinecone, or Qdrant.
- Chat with your graph. RAG over the user's own notes, with citations back to specific block IDs so answers stay verifiable.
- Summarization and synthesis. Roll up a week of daily notes, or generate an outline from a cluster of related blocks.
- Cleanup assistance. Detect near-duplicate pages, suggest merges, propose tag taxonomies.
Two cautions. First, privacy: knowledge bases contain people's most personal thinking. Be explicit about what leaves the device, offer local model options, and never train on user data without opt-in consent. Second, restraint: AI that writes for users undermines the whole point of a thinking tool. Aim to augment retrieval and connection, not replace cognition.
Step 7: Plan for Data Ownership and Export
PKM users are unusually sensitive about lock-in, and Roam took real reputational damage on this front. Treat export as a first-class feature:
- Markdown export with wiki-link syntax preserved
- JSON/EDN export of the full graph including block IDs
- Importers for Roam JSON, Obsidian vaults, Notion exports, and Evernote
- A documented API so power users can build their own tooling
Strong import paths also double as your best acquisition channel — make switching from a competitor a two-click operation.
Step 8: Monetization
- Subscription. The standard model. $5–15/month, often with annual discounts. Roam's "Believer" tier ($500 for five years) built early cash flow and community loyalty.
- Freemium. Free tier limited by note count, sync devices, or AI credits.
- One-time license plus paid sync. Obsidian's model: the app is free for personal use, sync and publish are paid add-ons. Builds enormous goodwill.
- Team plans. Shared graphs, permissions, and admin controls command significantly higher per-seat pricing.
- Usage-based AI. Charge separately for AI features to cover inference costs.
Development Timeline and Cost
Rough estimates for an experienced team:
| Phase | Scope | Timeline |
|---|---|---|
| Discovery & design | Research, UX, data model | 3–5 weeks |
| MVP web app | Block editor, links, backlinks, daily notes, search | 10–14 weeks |
| Sync & accounts | Auth, multi-device sync, offline support | 5–8 weeks |
| Mobile app | Capture, read, light editing | 8–12 weeks |
| AI features | Embeddings, semantic search, suggestions | 4–6 weeks |
| Polish & beta | Performance, import/export, QA | 4–6 weeks |
A focused web MVP typically lands in the $45,000–$90,000 range. A full cross-platform product with sync, mobile apps, and AI features more commonly runs $120,000–$250,000+, depending on team location and how ambitious the collaboration story is.
Common Pitfalls
Underestimating the editor. Teams routinely budget two weeks for "the text editing part" and lose two months. Outliner editors have enormous edge-case surface area.
Ignoring performance until late. Test with synthetic graphs of 50,000+ blocks from week one. Retrofitting virtualization and incremental indexing into a finished app is painful.
Shipping a feature clone. Roam's community, templates, and plugin ecosystem were a huge part of its moat. Features alone won't reproduce that.
Neglecting onboarding. Networked note-taking has a real learning curve. Ship a pre-populated demo graph, inline hints, and a guided first-week experience, or churn will be brutal.
Overcomplicating the first release. Queries, plugins, spaced repetition, and multiplayer can all wait. Blocks, links, backlinks, daily notes, and fast search are enough to be genuinely useful.
Final Thoughts
Building an app like Roam Research is less about replicating a feature list and more about honoring a philosophy: ideas are more valuable when connected, and the tool should get out of the way. Nail the data model, obsess over editor feel, respect user ownership of their data, and use AI to strengthen connections rather than manufacture content.
Start narrow. Serve one audience extraordinarily well. The graph — and the community around it — will grow from there.
Have a project in mind? Contact Sodio Technologies to discuss your requirements and explore the right technology solution for your business.
/// Work with us
Talk to the engineers who'd build it
You'll get a technical scope, timeline and cost estimate from the people doing the work, not an account manager. In-house team, no subcontracting, since 2016.